Start with the decisions your agents will make
Most enterprise agent projects resemble RPA with extra flexibility. Capture an existing process and execute it without the human cost.
With the availability of general-purpose memory libraries, like Mem0 or the recently launched past.dev, agent loops can in theory improve from run to run without manual prompt, skill, or tool-set tuning.
With evaluation and action loops, the promise extends to self-driving departments end-to-end. PostHog and Amplitude are building toward that loop for product teams, connecting usage signals to proposed changes and evaluation.
General purpose memory implementations are a great building block, especially for simple flows and personal AI, but fail to drive learning loops in more complex environments. We’ve been building deal-specific memory at Hindsight. This blog compares the building blocks for agent memory in general-purpose and domain-specific applications, focusing on GTM as the illustrative example.
We suggest working backwards from the decisions your agents will be making. Invest first in domain-specific event interpretation and retrieval, and for ambitious teams, evaluation loops.
Retrieval is not the same as judgment
Before we were focusing on self-improving GTM processes at Hindsight, we were building general retrieval infrastructure at Baseplate.
A well-built agent could answer a question like “How should I position against this competitor?” by identifying deals against that competitor and using RAG to find specific positioning examples. We built it, and reps loved it.
But sales leaders saw missing judgement. One leader described the difference as A players versus B players.
- A B player follows the playbook and repeats what others have done.
- An A player studies comparable situations, judges what worked or could improve, and forms a perspective for this buyer.
A quote from a win does not establish causation. You might have won that deal, but that positioning exercise may not have been a decision driver in the deal. Retrieving a statement doesn’t actually answer the question of how a rep should position in a specific scenario. It repeats what someone else did.
This has the counterproductive effect of reinforcing the status quo, for better or worse. We saw this repeatedly with initial versions of Hindsight. Enablement would build battlecards using evidence from deals, basically summarizing what their teams were already doing instead of learning from it.
Memory systems need to first capture, then interpret events. That process differs greatly between a support chat thread and a B2B deal with multiple touchpoints, conversations, and characters.
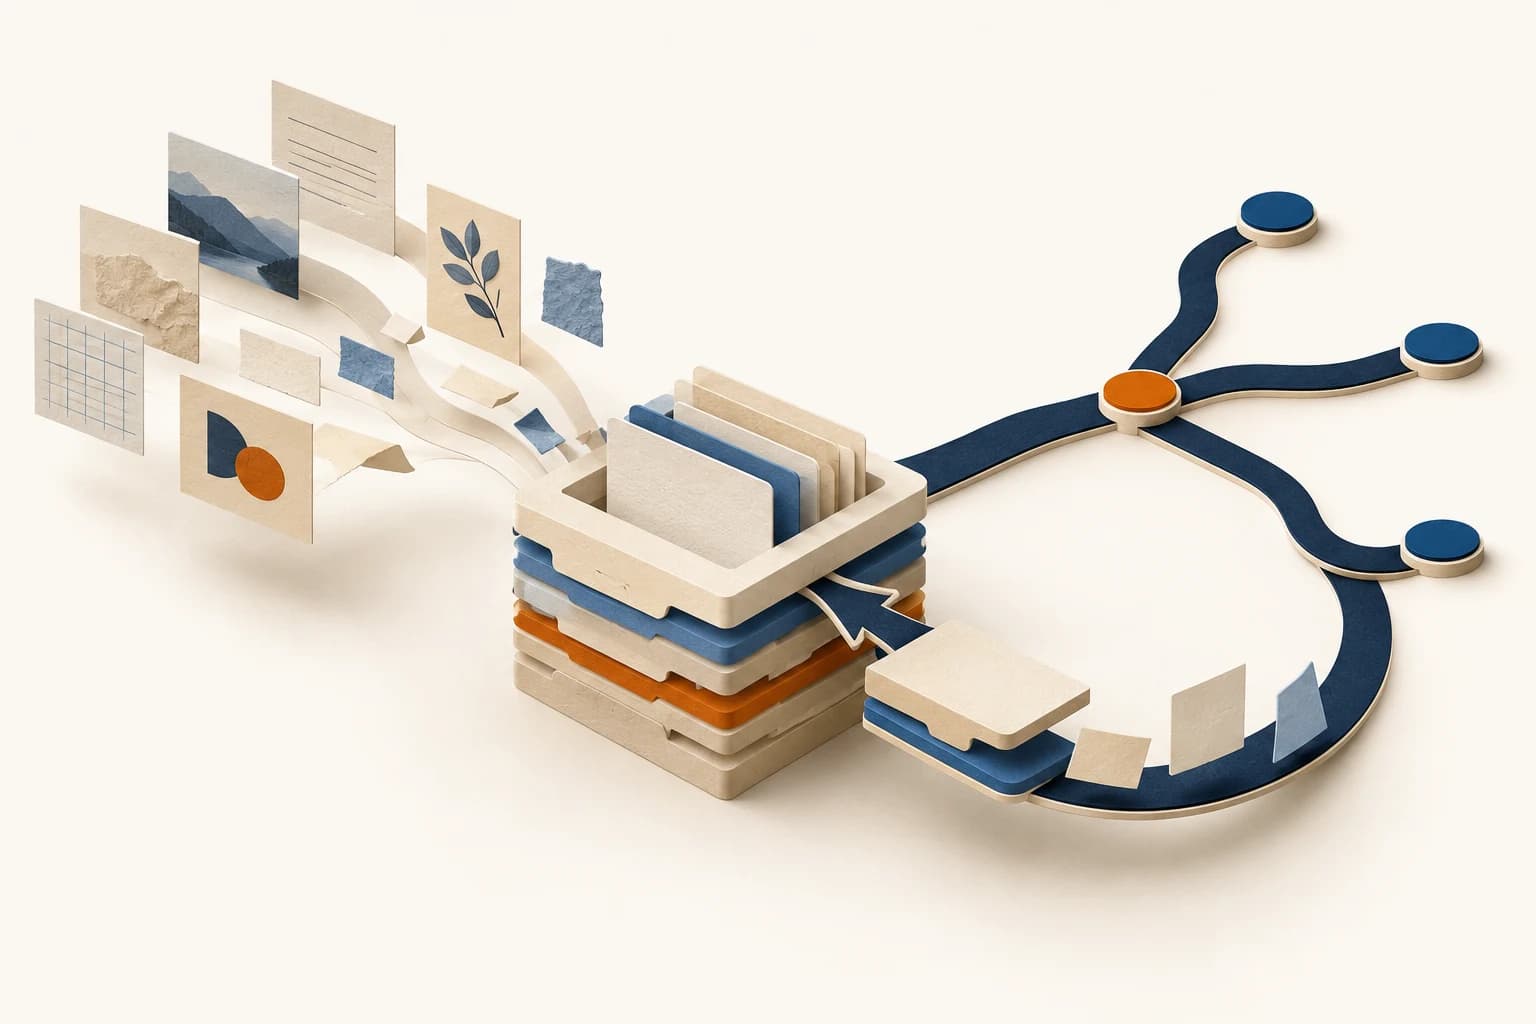
The four operations of agent memory
Memory platforms provide increasingly capable extraction, consolidation, and retrieval. Vectorize, Mem0, and Past.dev illustrate overlapping approaches. I find four operations useful for connecting that infrastructure to an application.
- Event Capture. Every memory system starts with Events. That could be a chat thread, a call transcript, or the touchpoints across a deal. Designing the event is the foundation. What context do you need? And how do you maintain provenance? Do you need source context at retrieval time or will synthesized memory suffice? See how Past.dev makes timestamped sources and supporting excerpts central to its model.
- Event Interpretation. An LLM turns the event’s context into a smaller set of useful statements, which we’ll call Observations. The question is what the model should extract or assess. This is where domain specificity makes a massive difference, and general purpose approaches can fall short. See how Mem0 extracts reusable information from conversations.
- Synthesis. One event creates multiple Observations that might help in the next run. Across events, we look for patterns and emerging trends, which we’ll call Learnings. Observations go through another round of analysis to identify those patterns and the conditions where they apply. This background process is sometimes called Dreaming. See how Vectorize consolidates observations and Mem0’s hosted Dream synthesizes patterns.
- Retrieval. Approaches here differ, but agents need access to Learnings, Observations, or Events at runtime. Knowledge graphs, trees, RAG, and grep-style search all work depending on the use case.
Most memory systems stop here. And there’s a lot to build, so the incentive to integrate a pre-built solution is strong, even if it might cut corners for your specific domain.
Events
Capture the full context
Observations
Interpret what mattered
Learnings
Synthesize across events
Decisions
Retrieve for the next action
What changes when the event is a deal
Let’s compare a deal to a support thread. A support thread might contain one problem, a sequence of attempted fixes, and a resolution. A B2B deal can span months of calls, emails, CRM notes, and different stakeholders. Even after it closes, the outcome may leave the reasons unclear. That changes how we build each part of the system:
- Event Capture. We treat the full deal as the event, rather than an individual document, and update it as the deal progresses. Some context doesn’t exist in the records, so we fill gaps with win-loss interviews. We also prioritize sources based on provenance and proximity to the decision. Even call transcripts need interpretation: buyers and sellers can hide what they’re thinking.
- Interpretation. A single summarization prompt wasn’t enough. Useful Observations required the deal context alongside sales playbooks, rubrics, and product taxonomy. We built a deal review agent with an orchestrator and specialized subagents that examine execution, product, pricing, and competition. We reconcile their findings into a deal story, while retaining the granular Observations, supporting evidence, and confidence levels.
- Synthesis. Broad patterns aren’t enough. We need cohort-specific analysis by buyer, segment, product, competitor, and other relevant conditions. This builds towards a working world model with revisable expectations about what might work in a new deal. The scope of a Learning is a scenario, rather than just a user.
- Retrieval. Comparable Deal Matching combines semantic similarity with factors such as use case, persona, segment, and competitor. Teams can tune those factors to find the experiences relevant to the current deal. Agents can retrieve Learnings directly, alongside Observations and source Events when needed. For a full-fledged system, we recommend combining that retrieval with maintained playbooks, so agents have both an established approach and evidence that may call for adapting it.
What we get is a memory system that preserves the principles of general purpose memory, but is designed to perform well for GTM teams. Now, in theory, our agents have the tools to learn and recommend or execute the “Next Best Step” for a specific deal.
Close the loop with evaluation
That still leaves effectiveness as a gray area. You might need to build your own evaluation system and loop to reach your self-driving vision. PostHog and Amplitude are building toward loops that connect product changes to measurement and experiments. We’re building our own evaluation system on top of Deal Memory and action-oriented workflows.
- Versioned playbooks. This might be a set of skills, a set of markdown files in a git repo, or something like Playbooks in Hindsight. We need a system to take Learnings and turn them into hypotheses about how we should work to achieve our goals—in our case, win deals. Agents can compose and edit these versioned playbooks, with people approving changes to organizational procedures.
- Experimentation. We need to apply our playbooks the way a PLG product team experiments with onboarding and CTAs. Identify a holdout group and a treatment group, and apply the published and experimental versions of your playbook to comparable cases. Some agent runs get the new one.
- Measurement and evals. Identify the behavior we’re trying to change or the metric we’re trying to move. This could be qualitative, like better customer discovery, but we need a way to assess it. We use LLM judges to score custom metrics from 1–5 and collect user feedback as well. Define acceptance criteria before the experiment, then evaluate once there’s enough evidence. If the new playbook meets those criteria, publish it as the canonical version.
Let decisions shape the next memory
These might seem like two different systems—memory and action. But they are closely linked in well-functioning systems. The same playbook we use to guide actions is used to interpret events. Interpretation and synthesis need to account for which version was followed, what actions were taken, and what happened next. Retrieval needs to find the right memory at the right granularity for the action. Results then feed back into the next round of Learnings.
An agent can already tailor a “Next Best Step” to the current deal, retrieve some memories, and consult a sales playbook or battlecard. But the Learnings might be too generic for this buying scenario, the playbook might be outdated, and you might have no idea whether the advice was used—or whether it worked.
With a memory system built for the use case, the current deal’s Events help identify comparable scenarios and retrieve the Learnings that apply. The agent combines those with the current playbook to recommend an action. We can then track whether that action was taken and what happened afterward. That evidence feeds back into interpretation, synthesis, and the next set of Learnings and playbook updates.
Current deal + comparable experience
Retrieve the Learnings that apply to this scenario.
Versioned playbook + next best step
Recommend an action using the current approach and evidence.
Action + measured outcome
Track what was used, what happened, and which version guided it.
Feed the evidence back into interpretation, Learnings, and the next playbook version.
The data is early, but we’re seeing large improvements in memory quality and much more relevant recall. Treatment groups have an 8% higher win rate relative to baseline. There’s still more to learn about where the improvements hold, but we can now evaluate the loop against what it’s meant to achieve: better decisions and outcomes.
We’re getting closer to the holy grail: an agent that can identify the Next Best Step like an A player, learn from what happens when it’s used, and share those Learnings with everyone else.